Why Neural Networks Need More Than Answers
When a model is asked, “What is 17 × 24?” a correct answer alone gives little evidence about how it arrived there. It may have performed a reliable calculation, recalled a familiar pattern, or produced a plausible guess. That distinction matters more when the task involves several conditions, unfamiliar information, or a sequence of dependent decisions.
Neural networks generate text one token at a time, so an answer can appear fluent even when the underlying computation is incomplete. Intermediate steps provide temporary structure: they can hold partial results, expose assumptions, and make errors easier to detect before they affect the conclusion. This does not give the model human understanding, and extra text can still contain invented or inconsistent steps. The practical question is therefore not whether a response sounds reasoned, but whether its intermediate structure supports the required computation.
What Chain-of-Thought Adds Between Input and Output
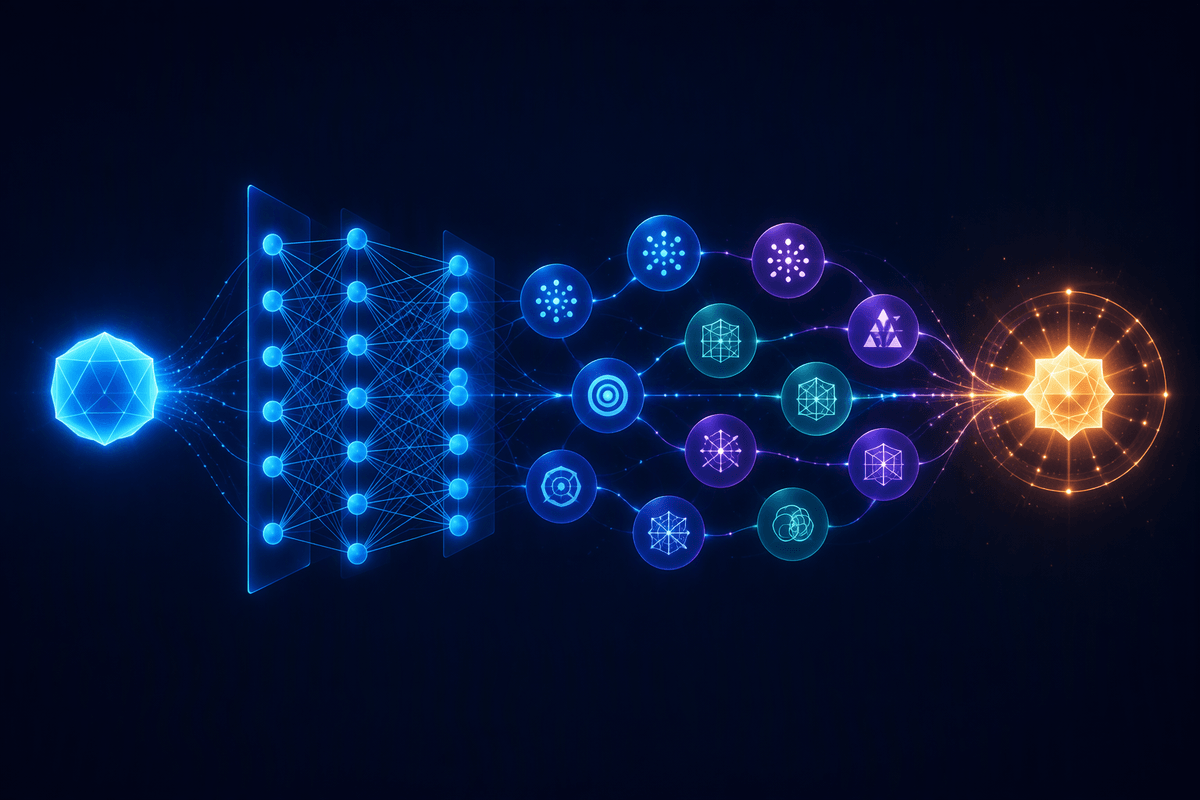
Chain-of-thought adds a sequence of intermediate statements between the question and the final answer. Instead of mapping “A train travels 60 miles in 1.5 hours” directly to “40 miles per hour,” the model may first identify the relevant quantities, write the relationship, and then divide distance by time. Each step creates additional text that the model can use as working material. Later predictions can attend to those earlier results, rather than relying on one compressed guess.
This structure is especially useful when the answer depends on several linked operations. A model solving a logic puzzle, for example, can track which conditions have been applied and carry partial conclusions into the next step. The benefit comes from organizing computation across multiple predictions, not from the words “let’s think” acting as a special mental command. Yet an intermediate sequence is only useful if it stays consistent with the problem. A model can produce polished steps that use the wrong formula, overlook a condition, or rationalize an answer chosen for other reasons. Chain-of-thought therefore supplies a possible workspace, not a guarantee of correct reasoning.
Breaking Difficult Problems Into Smaller Computations
A difficult problem often becomes manageable when its dependencies are made explicit. Consider a word problem involving several purchases, a discount, and sales tax. A direct answer requires the model to combine prices, apply the discount in the correct order, and calculate the final charge. Breaking it apart creates smaller computations: add the item costs, subtract the discount, then apply tax to the resulting subtotal. Each intermediate value narrows what the next step needs to do.
This decomposition can reduce the burden on any single prediction. It also gives the model repeated opportunities to preserve relevant details, such as units, conditions, or earlier results. In programming, the same principle appears when a large task is divided into functions with clear inputs and outputs. However, smaller steps do not automatically make the computation sound. If the model misreads the original condition, every later step may faithfully build on that mistake. More steps also increase the number of places where arithmetic, ordering, or transcription errors can occur. The advantage comes from useful structure and verification, not from length alone.
Why Extra Steps Can Improve Accuracy
Extra steps can improve accuracy because they give the model more chances to check whether the result still fits the problem. In a multi-step calculation, an intermediate total can reveal an obvious mismatch: a negative quantity where none is possible, a percentage applied to the wrong amount, or a final value that exceeds a stated limit. A structured solution also makes it easier to compare each operation with the wording of the question instead of treating the answer as one indivisible prediction.
This benefit resembles using a scratchpad, but it has an important qualification. The model is not necessarily verifying its work with a separate, dependable process. It may repeat the same mistaken assumption in several forms, or generate a convincing explanation after arriving at an answer through a shortcut. Extra steps can even reduce accuracy when they introduce unnecessary arithmetic or distract from a simple relationship. Reliable improvement usually comes when the steps match the problem’s actual structure and include checks that can fail visibly. For higher-stakes tasks, external tools such as calculators, code execution, or rule-based validation may provide stronger safeguards than additional prose alone.
The Role of Training, Prompts, and Representations
Whether chain-of-thought helps depends partly on what the model learned during training. Models exposed to many worked examples may learn that certain tasks are easier when they identify quantities, apply rules, and preserve intermediate results. A prompt can encourage that behavior by requesting a step-by-step solution, supplying an example, or asking the model to check its answer. The prompt does not install a new reasoning module; it changes which learned patterns are more likely to be activated and continued.
A problem written as plain language may be harder to solve than the same problem expressed in a table, equation, list of constraints, or short program. These formats make relationships and variables easier to track, reducing ambiguity before computation begins. Still, training and prompting have limits. A model may imitate the style of a worked solution without performing the underlying operations, especially when the task differs from familiar examples. A detailed prompt can also consume context, introduce distracting assumptions, or encourage confident explanations of an incorrect interpretation. Useful reasoning structure therefore depends on alignment between the representation, the learned procedure, and the problem itself.
When Visible Reasoning Fails or Misleads
A step-by-step answer can look persuasive while still being wrong. A model may state an incorrect premise, apply a rule backward, or quietly change the meaning of a key term. Once that error appears early, later steps can remain internally consistent without matching the original problem. This is particularly risky when readers treat fluent explanations as evidence that the model actually performed the computation.
Visible reasoning can also mislead by presenting a post hoc explanation. The model may arrive at a likely answer through learned associations, then generate steps that make the result sound justified. Those steps are useful only when they can be checked against the inputs, rules, or an independent method. For example, arithmetic should be verified with a calculator or code, and a legal or technical conclusion should be compared with the relevant source rather than accepted because the explanation is detailed. Longer reasoning is not automatically better reasoning: it can amplify an early misunderstanding, introduce extra errors, or hide uncertainty beneath confident language. The practical test is whether the intermediate work exposes verifiable relationships and supports a result that survives independent checking.
A Practical View of Reasoning as Computation
When evaluating a chain-of-thought solution, treat it like a computation trace rather than a window into private thought. Ask whether each step uses the right inputs, preserves the relevant constraints, and produces a result that the next step can legitimately use. For a budgeting problem, that might mean checking the subtotal, discount, tax rate, and final total separately. The intermediate text is valuable because it makes these dependencies inspectable, not because every sentence proves genuine understanding.
This view also sets realistic expectations. Chain-of-thought can provide structure, reduce working-memory demands, and improve performance on some multi-step tasks, but it cannot replace reliable procedures or independent checks. The strongest workflow combines clear representations, concise intermediate computations, and tools suited to the task. Reasoning helps most when it functions as organized, testable work—not merely as a longer explanation.