Why Autonomy Starts With Business Outcomes
Many organizations begin with a promising AI tool and then search for somewhere to deploy it. That approach often produces an impressive demonstration but little operational value. Autonomy should begin with a business outcome that matters: reducing order exceptions, improving maintenance uptime, shortening claims handling, or helping service teams resolve issues on the first contact.
Starting there forces useful choices. Leaders can identify the decision to automate, the information it requires, the acceptable error rate, and the person who remains accountable when conditions change. It also exposes constraints early. A process that depends on incomplete customer records, manual handoffs, or unwritten judgment cannot become reliably autonomous simply because a model is available. The objective is not fewer people touching work; it is better, more dependable business performance.
Choose Decisions Worth Automating First
A familiar temptation is to start with the most visible or complex decision in a process: approving credit, rerouting shipments, or changing production schedules. Those decisions may eventually benefit from automation, but they are rarely the best starting point. Begin with decisions that occur often, follow recognizable patterns, have measurable outcomes, and can be reversed or reviewed when needed. Routing a routine service request, matching an invoice to a purchase order, or prioritizing standard maintenance work can create value while exposing the real operating requirements.
Does the decision have a clear owner, reliable inputs, an agreed definition of a good outcome, and a practical fallback when confidence is low? If the answer is no, automation will likely amplify inconsistency rather than remove it. High-volume work with bounded risk gives teams room to learn how exceptions appear, where people add essential judgment, and which controls actually matter. The first target should not be the decision that sounds most advanced. It should be the one that can prove reliability, improve performance, and build confidence for more consequential automation.
Fix the Data and Process Gaps
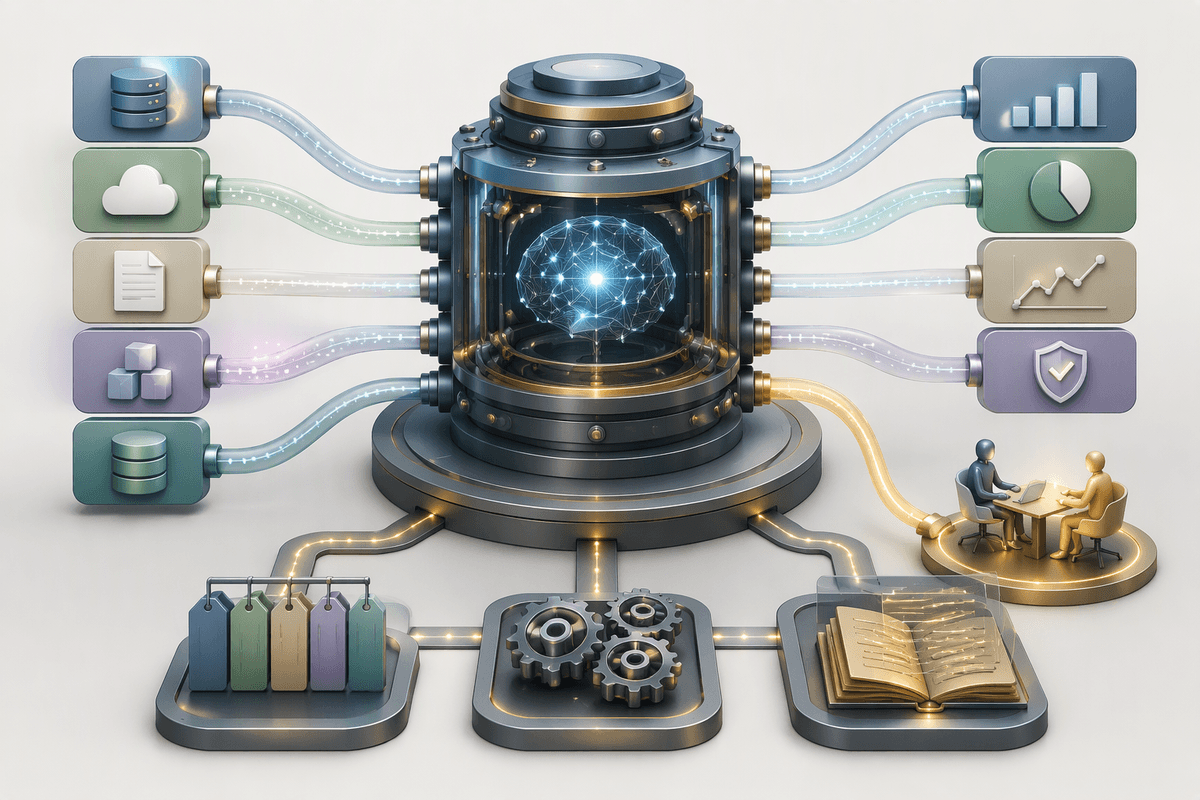
A routine decision can look ready for automation until the team traces where its inputs actually come from. Customer status may live in three systems, inventory updates may arrive hours late, and experienced employees may resolve exceptions through email or informal conversations. An AI agent cannot compensate consistently for conflicting records or steps that exist only in someone’s memory. It will act on whatever information and rules it can reach.
Start by mapping the decision from trigger to outcome: the source data, system handoffs, approval points, common exceptions, and the record that confirms completion. Then fix the gaps that most affect reliability. That may mean assigning ownership for key data fields, standardizing reason codes, connecting a workflow to the system of record, or documenting when work must move to a person. This work is rarely glamorous, and integration, cleanup, and process redesign take time and budget. But it turns a promising automation use case into an operation that can produce repeatable results, be audited when necessary, and improve as conditions change.
Build a Technology Stack That Connects
Once a workflow has dependable inputs and defined handoffs, the technology question becomes practical: can the systems involved exchange information and trigger action without fragile workarounds? In many organizations, the answer is only partly. Core records sit in ERP, CRM, service, and operational platforms that were built for people to navigate, not for automated agents to coordinate. A connected stack gives automation secure access to the right data, workflow tools to route work, and APIs or integration layers to update the system of record after a decision is made.
Prioritize capabilities that make work visible and controllable across those systems: identity and access management, event-based integrations, workflow orchestration, logging, monitoring, and a clear way to handle failures. Avoid treating a general-purpose AI interface as the stack itself. It may interpret a request well, but it still needs approved tools, current context, and reliable execution paths. Integration work can be expensive and legacy platforms may impose real limits, so focus investment on the few connections that support high-value decisions first. The goal is not a perfectly modern architecture; it is a dependable path from insight to action and back to a recorded business outcome.
Set Guardrails Without Slowing Progress
When an automated workflow can read customer records, initiate a payment hold, or change a delivery plan, leaders face a familiar tension: move quickly enough to learn, but not so quickly that a small error becomes an operational or compliance problem. The answer is not a long approval chain for every action. It is to define clear boundaries before deployment: which systems the automation may access, what actions it may take independently, when it must ask for confirmation, and when it must stop and hand work to a person.
Make those boundaries specific to the decision’s risk. A service agent might automatically classify and route routine requests, while refunds above a set amount require approval. A supply-chain agent might recommend an expedited shipment but need authorization before committing additional cost. Require identity controls, complete action logs, testing with realistic exceptions, and monitoring for unusual behavior. Review thresholds and rules regularly as volumes, regulations, and performance change. Good guardrails do not make automation passive; they give teams a safe operating range in which it can act consistently, learn from outcomes, and earn permission to handle more.
Redesign Roles Around Human and AI Work
When routine work begins to move through automated workflows, the first concern is often whether jobs will disappear. The more immediate question is how jobs will change. A claims specialist who once spent most of the day gathering documents may instead review uncertain cases, correct weak inputs, and identify patterns behind repeated exceptions. A planner may spend less time assembling reports and more time deciding when an automated recommendation does not fit current market or customer conditions.
Design those changes deliberately. Define which tasks the automation performs, where people must approve or intervene, who owns outcomes, and how feedback from employees improves the workflow. Give teams training not only on the tools, but also on how to challenge an AI-generated action, document an exception, and recognize when a result falls outside normal conditions. This takes time and can create short-term workload pressure while old and new ways of working overlap. Still, treating workforce design as an operating change rather than a staffing exercise helps preserve essential judgment, build trust, and make automation more reliable as its scope expands.
Scale Proven Capabilities, Not Isolated Pilots
A pilot can show that an AI workflow works in one team, with clean data, close supervision, and a small set of exceptions. Scaling tests something harder: whether the organization can repeat that result across locations, business units, and changing conditions. Before expanding, confirm that the workflow has delivered measurable value, stayed within its guardrails, and has clear ownership for its data, controls, and performance.
Turn what worked into a reusable capability: shared integration patterns, approved access controls, monitoring measures, training materials, and a disciplined method for handling exceptions. Expand one decision type or process area at a time, rather than launching many unrelated pilots. This may feel slower initially, especially when local teams want tailored solutions. But a common operating foundation reduces duplication, makes results easier to compare, and lets each successful deployment strengthen the next.