Why Smart Systems Still Need Simple Foundations
A system can recognize a face yet struggle to understand that a cup remains the same object when it moves behind a hand. It may generate fluent advice but misread a simple instruction because it lacks a clear sense of sequence, quantity, or context. These gaps are not always signs that the system needs a larger algorithm. Often, they reveal weaknesses in its foundations: unclear goals, uneven examples, or missing basic concepts.
Reliable learning depends on more than processing power. A model needs useful information, meaningful structure, and feedback that distinguishes a good answer from a plausible mistake. Foundational knowledge can narrow confusion and make training more efficient, but it does not remove the need for careful data or testing. Even advanced systems remain shaped by what they are shown, what they are asked to do, and how their errors are handled.
Start With the Problem, Not the Algorithm
When a machine-learning project goes wrong, the first question is often, “Which model should we use?” A better starting point is, “What exactly should the system do?” A tool designed to sort urgent messages has a different problem from one designed to summarize classroom discussions, even if both use similar algorithms. Without a clear goal, training data may reward the wrong behavior, and impressive performance numbers may hide failures that matter in daily use.
Defining the problem also clarifies what the system must understand. A delivery model may need to distinguish a late package from a damaged one, while a tutoring system must recognize whether a student made a calculation error or misunderstood the underlying idea. These distinctions shape the examples, labels, and tests used during training. Starting with a sophisticated algorithm can add cost and complexity before anyone knows whether the basic task has been framed correctly. A simpler system with a precise objective often provides a more reliable foundation—and a clearer way to see what still needs improvement.
Clean, Representative Data Does the Heavy Lifting
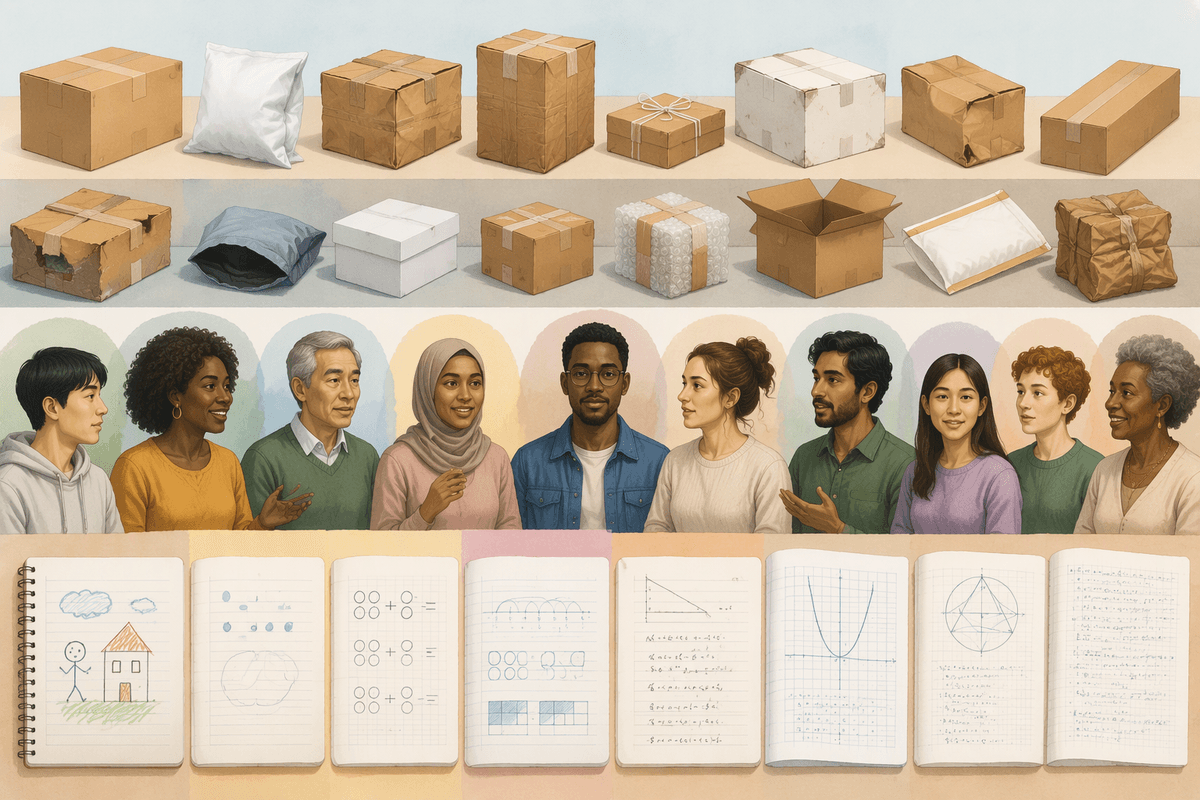
Once the task is clear, the quality of the examples becomes decisive. A system trained to identify damaged packages cannot learn much from thousands of photographs showing only clean boxes in bright light. It needs examples of torn labels, crushed corners, poor camera angles, and ordinary packages that should not be rejected. The data must reflect the conditions the system will actually encounter, not an idealized version of them.
Representation matters as much as volume. If a classroom tool is trained mostly on advanced answers, it may overlook the partial reasoning that shows how beginners learn. If a speech system hears one accent far more often than others, its accuracy may vary for reasons unrelated to the speaker’s meaning. Labels can create similar problems when people apply them inconsistently or when important categories are missing. Cleaning data takes time, and collecting balanced examples can be expensive, but adding more flawed data often increases confidence without improving judgment. A smaller, carefully reviewed dataset may therefore provide a stronger foundation than a much larger one that quietly encodes gaps, noise, or misleading patterns.
Give the Model Useful Ways to See
A model can have plenty of examples and still miss what matters if those examples are presented in unhelpful forms. Consider a system learning to identify a bicycle. A single label such as “bicycle” may be less useful than information about wheels, handlebars, frame, position, and how those parts relate. These features give the model several ways to recognize the object, even when part of it is hidden or viewed from an unusual angle.
This kind of structure helps with language as well. A tutoring system may learn more from an answer paired with the student’s reasoning, difficulty level, and the step where an error occurred than from a simple mark of right or wrong. Useful representations do not guarantee understanding, but they reduce the number of patterns the model must discover on its own. Designing them requires judgment: too little structure leaves important relationships invisible, while too much can make the system rigid or costly to maintain. The practical goal is to expose the concepts and connections most relevant to the task, without assuming that every detail deserves equal weight.
Test Simple Approaches Before Adding Complexity
When a model performs poorly, adding more layers or tuning more parameters can seem like the obvious solution. Yet a simple baseline often reveals whether complexity is needed at all. A rule-based filter, a basic statistical model, or a short decision tree may handle common cases and expose where the real difficulty lies. If a simple approach performs nearly as well as a complex one, the added machinery may bring more maintenance, cost, and opportunities for hidden errors than useful improvement.
Simple tests also make failures easier to interpret. A delivery system that first uses package weight, destination, and shipping history can show whether delays are mainly predictable or whether important information is missing. Only after that evidence should developers consider a more elaborate model. Complex systems can detect subtle patterns, but they usually require more data, computing power, monitoring, and explanation. They may also fit accidental quirks in the training set. Comparing methods on realistic, separate test data helps determine whether extra complexity improves decisions outside the examples used for learning, rather than merely producing a better score in the development process.
Feedback Teaches the System What Matters
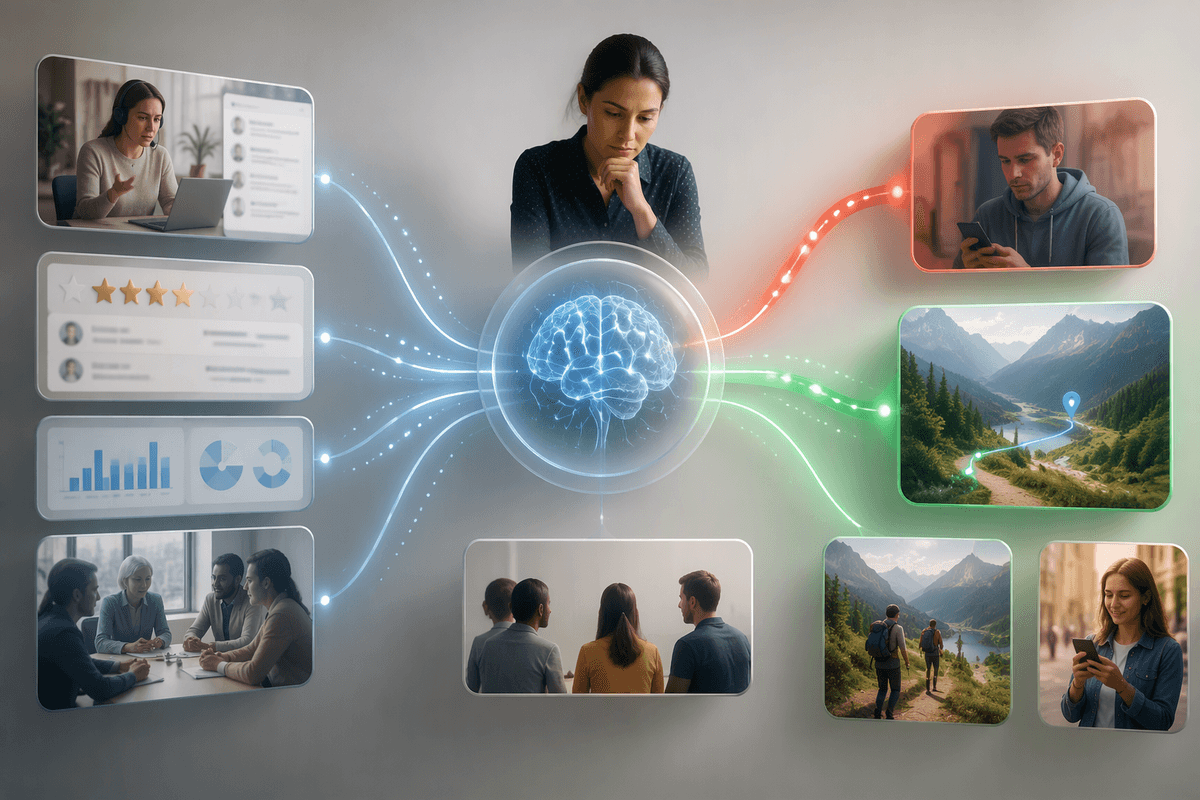
A system does not learn only from examples; it also learns from judgments about those examples. When a recommendation is accepted, corrected, or ignored, that response helps indicate which patterns are useful and which are misleading. In a tutoring tool, marking an answer wrong is less informative than showing whether the mistake came from a missed step, a faulty assumption, or an unclear question. Specific feedback gives the model a better target than a simple score.
Good feedback must also match the goal. If a customer-service system is rewarded mainly for answering quickly, it may produce confident replies that solve fewer problems. If a navigation system is judged only by distance, it may send drivers through unsafe or impractical routes. Feedback can come from people, later outcomes, or carefully designed tests, but each source has limits. Human reviews take time and may vary between reviewers; automated signals can be convenient while rewarding shortcuts. Reliable training therefore treats feedback as evidence to examine, not unquestionable truth. The quality of the learning process depends on whether the chosen signals reflect the behavior people actually need.
Better Learning Begins With Better Teaching
A model that struggles with a simple task may not need more intelligence so much as clearer instruction. Teaching involves choosing useful examples, naming important concepts, showing relationships, and correcting mistakes in ways the system can use. A student learns more from seeing why an answer is wrong than from hearing only that it failed; machine-learning systems face a similar constraint. Guidance must be specific enough to shape behavior without forcing the system into narrow patterns that fail in unfamiliar situations.
Creating thoughtful examples and reliable feedback requires time, expertise, and ongoing review, especially when real-world conditions change. Still, the basic principle is durable: better learning begins with better teaching. When evaluating claims about improved AI, look beyond model size and ask what the system was shown, how its performance was judged, and whether it learned concepts that transfer beyond its training examples.