Why Mechanistic Interpretability Matters in 2026
A model can pass benchmarks, produce polished answers, and still fail in ways its developers cannot explain. That gap matters more in 2026, as AI systems take on longer tasks, use tools, and operate with less direct supervision. Standard evaluations reveal what a model does, but not necessarily why it does it or whether a small change could trigger a serious failure. Mechanistic interpretability addresses that problem by examining the internal features, pathways, and circuits that support model behavior.
The practical value is not just better explanations. These methods could help teams detect hidden objectives, investigate unreliable reasoning, compare model versions, and identify risks before deployment. Progress remains uneven: internal mechanisms are difficult to map completely, automated analysis can produce misleading stories, and the cost of inspecting large models is substantial. The important question, therefore, is which techniques provide dependable evidence rather than attractive visualizations or plausible-sounding narratives.
What Counts as a Breakthrough Technology?
A breakthrough technology in mechanistic interpretability should do more than make a model’s internals easier to inspect. It should produce evidence that changes a real decision: whether to deploy a system, revise its training, restrict a capability, or investigate a failure. That usually requires three properties. The method must identify internal structures that correspond to meaningful behavior, test whether those structures actually matter, and work across enough models or tasks to support comparison. A compelling diagram is not sufficient if removing the highlighted component leaves the behavior unchanged.
Several approaches meet parts of this standard. Feature-discovery methods can reveal concepts distributed across many neurons, while circuit-tracing methods connect those concepts to specific computations. Automated tools can expand coverage, but they may also generate confident explanations from incomplete evidence. Practical value therefore depends on causal tests, reproducibility, and manageable cost. A technique that explains one small model perfectly may matter less for deployment than a rougher method that helps engineers find dangerous changes in a production-scale system. The strongest advances combine internal analysis with intervention, evaluation, and clear limits on what the evidence supports.
Finding Features Inside Model Activations
One useful starting point is to examine the model’s activations across many examples. Individual neurons may respond to several seemingly unrelated patterns, such as a programming keyword in one context and a grammatical structure in another. This “polysemantic” behavior makes neuron-level explanations difficult to interpret. Feature-discovery methods take a broader view, searching activation space for directions that correspond to more coherent patterns, such as concepts, relationships between tokens, or recurring stages of a computation.
Sparse autoencoders are among the most widely used methods for this purpose. Rather than treating individual neurons as the basic unit of interpretation, they reconstruct internal activations from a larger set of learned features and encourage only a small subset to activate for any given input. Those features are often easier to label and trace than raw neurons. Analysts can then increase or suppress individual features and observe whether relevant outputs change, giving causal tests more weight than simple correlations. Several uncertainties remain, however. One concept may be divided across multiple learned features, unrelated patterns may be combined, and some features may not be captured at all. Results also depend on choices made when designing the autoencoder. Feature labels therefore serve as useful working hypotheses, not definitive accounts of how the model processes information.
Tracing Circuits Rather Than Isolated Neurons
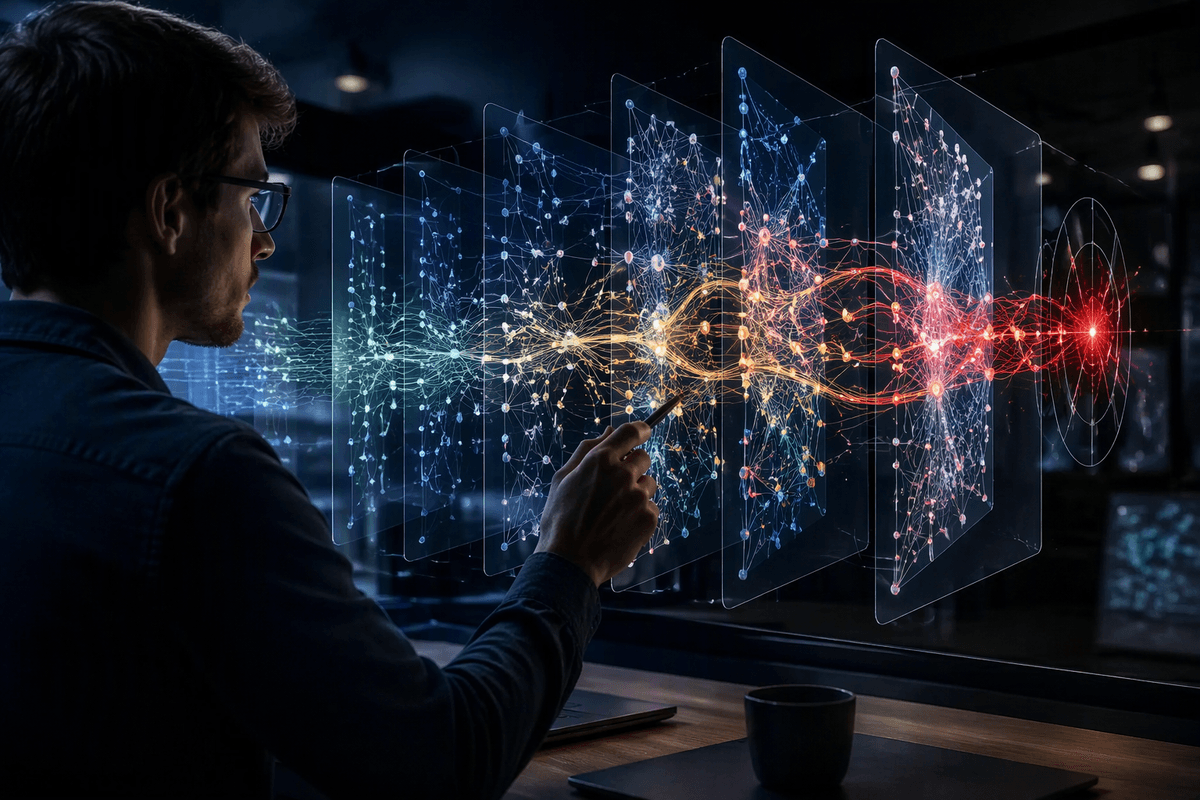
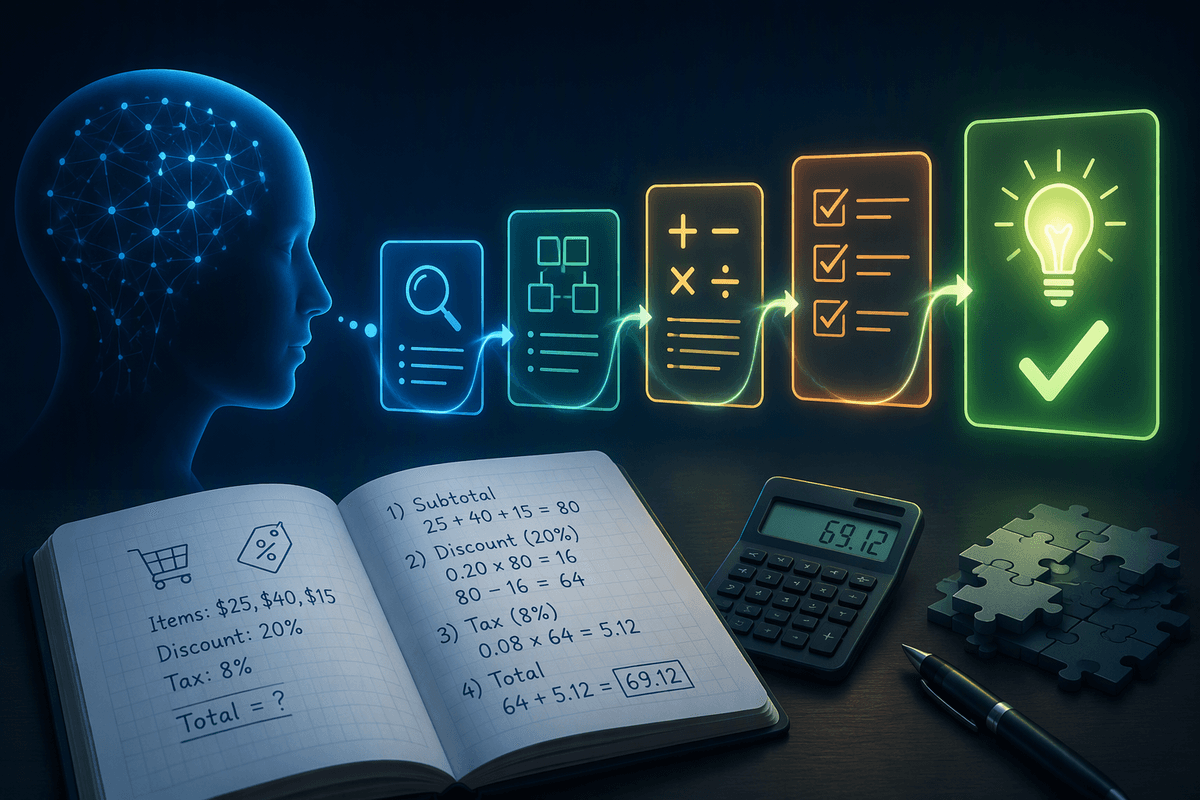
Suppose a model gives the right answer for the wrong internal reason. A feature associated with “Paris” may be active, but that does not show whether the model used it to retrieve a capital, predict a spelling pattern, or follow a memorized phrase. Circuit tracing addresses this gap by following information across layers and components. Researchers examine how attention heads, multilayer perceptrons, and identified features interact to produce a specific behavior, such as tracking an entity through a paragraph or carrying a value through a calculation.
The key advance is causal testing. Analysts can intervene on one part of a proposed circuit, replace an activation, or block a pathway, then measure whether the target behavior changes while nearby abilities remain intact. This helps distinguish a mechanism from a coincidental correlation. It also exposes an important limitation: large models often use redundant or context-dependent pathways, so one successful intervention may reveal only part of the computation. Circuit maps can therefore be valuable for debugging and comparison without being complete blueprints. Their practical importance grows when tracing connects feature-level discoveries to failures that engineers can reproduce, isolate, and potentially correct.
Turning Interpretability Into Model Debugging
A debugging workflow begins with a behavior engineers can reproduce: a model invents a citation, ignores a safety instruction, or changes its answer after an irrelevant prompt. Interpretability tools can then narrow the search from the final output to the internal features and pathways that differ between successful and failed cases. If a suspected feature or circuit appears only in failures, targeted interventions can test whether it contributes to the problem. This turns interpretability from a descriptive exercise into a way to prioritize experiments.
The most useful result is not always a complete explanation. It may be evidence that a model relies on a brittle shortcut, that a safety-relevant pathway is being bypassed, or that two model versions implement the same behavior differently. Teams can use those findings to adjust data, modify training objectives, add targeted evaluations, or block deployment until the issue is better understood. The process remains expensive and imperfect: debugging complex failures may require many carefully controlled prompts, and interventions can damage unrelated capabilities. Interpretability therefore works best alongside conventional testing, with causal evidence treated as a guide for remediation rather than a guarantee that every failure mode has been found.
From Explanations to Reliable Model Control
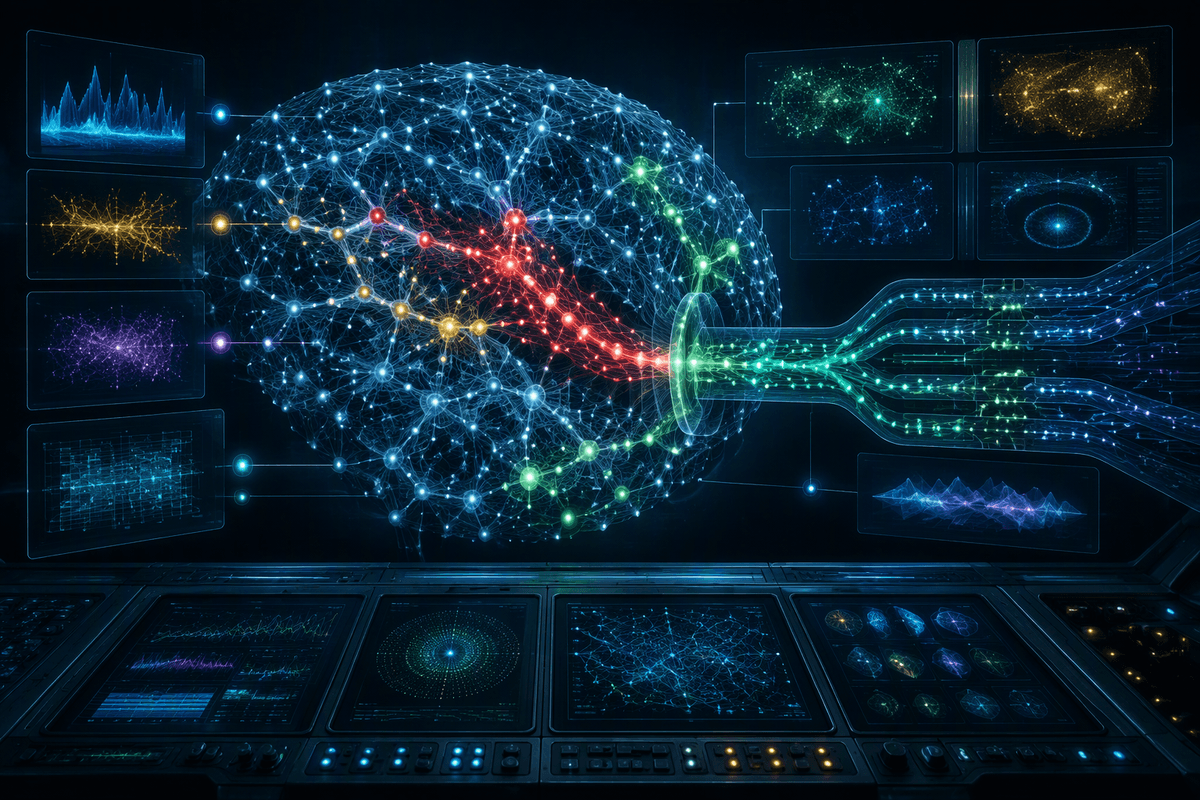
Once a mechanism has been linked to a failure, the harder question is whether engineers can control it without creating new problems. A team might suppress a feature associated with fabricated citations, strengthen a pathway used for following safety instructions, or redirect a circuit toward a more reliable computation. These interventions are more promising than broad retraining when the problem is narrow and well understood. They can also support deployment controls, such as checking whether a safety-critical feature is active before allowing a model to complete a sensitive task.
Reliable control requires more than changing an activation and observing a better output. The intervention must hold across prompts, tasks, and model versions, while preserving useful capabilities and resisting simple workarounds. A model may route around a blocked pathway, or the targeted feature may represent several behaviors that cannot be separated cleanly. For that reason, interpretability-based control should be paired with adversarial testing, regression checks, and monitoring after deployment. Its near-term value is likely to be selective: improving oversight of known risks and high-stakes behaviors, not providing a universal switch for model intent.
What Comes Next for Mechanistic Interpretability
The next meaningful advances will likely come from combining feature discovery, circuit tracing, and automated testing into repeatable evaluation pipelines. Instead of asking whether a model has been “explained,” teams will compare mechanisms across versions, test them under adversarial prompts, and monitor whether important pathways remain stable after fine-tuning or tool integration. Shared benchmarks and clearer causal standards will matter as much as new analysis tools, because progress is difficult to judge when each project uses different definitions of a successful explanation.
Mechanistic interpretability is therefore best viewed as an evidence layer for safety and deployment decisions, not a replacement for behavioral testing. Its strongest near-term contribution will be finding specific risks early enough to investigate, constrain, or retrain—while making uncertainty and coverage limits explicit.