Why Simple AI Is Changing Research
Researchers often turn to AI expecting a complicated system that can process vast amounts of data and produce an impressive prediction. Yet some of the most useful results come from simpler experiments: a model tests patterns in existing evidence, highlights an unexpected relationship, and gives researchers a clearer place to look. The value is not that the machine has solved the problem. It is that the system can expose assumptions or connections that are difficult to notice by reading studies one at a time.
That simplicity also makes the finding easier to inspect. Researchers can see what information shaped the result, test whether the pattern holds elsewhere, and identify gaps that still require human judgment. A simple model may miss important context or mistake correlation for cause.
The Research Problem AI Helps Expose
A familiar research problem appears when different studies seem to address the same question but use different terms, measurements, or populations. One paper may describe a biological process, for example, while another reports a related effect under a different name. Human readers can connect those clues, but doing so across thousands of articles is slow and easy to overlook. A simple AI system can compare the language and results across this scattered evidence, revealing that ideas treated as separate may be linked.
What it exposes is not necessarily a hidden fact, but a weakness in how the field is organized. The model may show that one relationship appears repeatedly, that certain groups are underrepresented, or that a popular explanation rests on surprisingly little evidence. That signal still needs careful checking. The data may contain publication bias, inconsistent definitions, or studies that copied the same original assumption. AI can make the gap visible, but researchers must determine whether it reflects a genuine pattern, a measurement problem, or simply an artifact of the available literature.
What Makes the Approach Surprisingly Simple
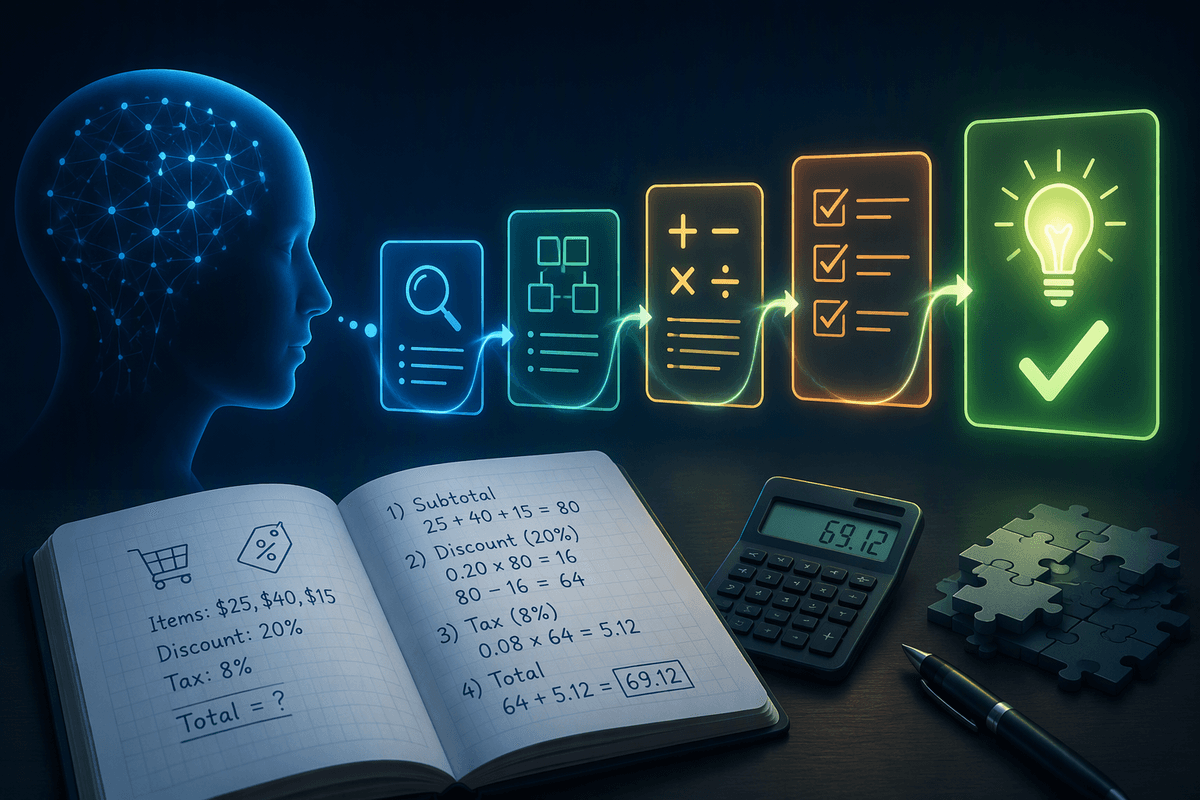
The surprising part is often what the system does not need. It may not require a massive language model, a new data-collection program, or a fully automated chain of reasoning. Researchers can start with a defined set of papers, convert their findings into comparable features, and use a straightforward model to identify recurring relationships. The model’s job is closer to sorting and comparing than to independently discovering a theory.
That limited role can be an advantage. Because the inputs and comparisons are easier to describe, researchers can inspect why a pattern appeared and test it against another dataset or group of studies. A simpler method may also reveal a useful connection without burying it under layers of technical complexity. But simplicity does not remove the need for careful design. The choice of papers, labels, measurements, and comparison rules can shape the result before the model runs. If those choices are narrow or biased, the system may produce a clean-looking pattern that says more about the dataset than about the underlying problem.
Where Human Judgment Still Matters Most
A model can flag an important relationship, but it cannot decide what that relationship means in the real world. Researchers still need to judge whether the studies used comparable methods, whether the pattern makes biological or social sense, and whether another explanation fits the evidence better. A connection between two terms may reflect a genuine mechanism, or it may simply appear because both were discussed in the same influential papers.
Human judgment becomes especially important when deciding what to test next. Researchers must choose which result deserves a follow-up experiment, which population or dataset could challenge it, and how much uncertainty is acceptable. They also need to notice what the model cannot see, such as missing measurements, unusual cases, or practical conditions that were never recorded. This work takes time and may lead to a less dramatic conclusion than the original AI output. That restraint is part of the method’s value. The system narrows the search, while people assess the evidence, design stronger tests, and decide whether the finding can support a useful claim.
A Useful Finding Is Not Always a Final Answer
That distinction matters when a model produces a result that looks convincing but has not yet been tested outside the material used to find it. A recurring link in published studies may help researchers form a strong hypothesis, yet it does not show that changing one factor will produce a particular outcome. The finding becomes useful because it changes what researchers examine, not because it settles the question.
Follow-up work can expose several limits. The pattern may disappear in a different population, depend on a measurement that was used inconsistently, or fail when researchers control for another variable. Even a relationship that survives those checks may be too small or costly to matter in practice. Confirming it could require new experiments, better records, or years of observation. That does not make the original AI analysis a failure. It gives the result an appropriate role: a map of promising terrain, with uncertainty clearly marked. Researchers can then build a more focused study around the signal instead of treating a convenient correlation as a finished explanation.
How Other Researchers Could Apply the Lesson
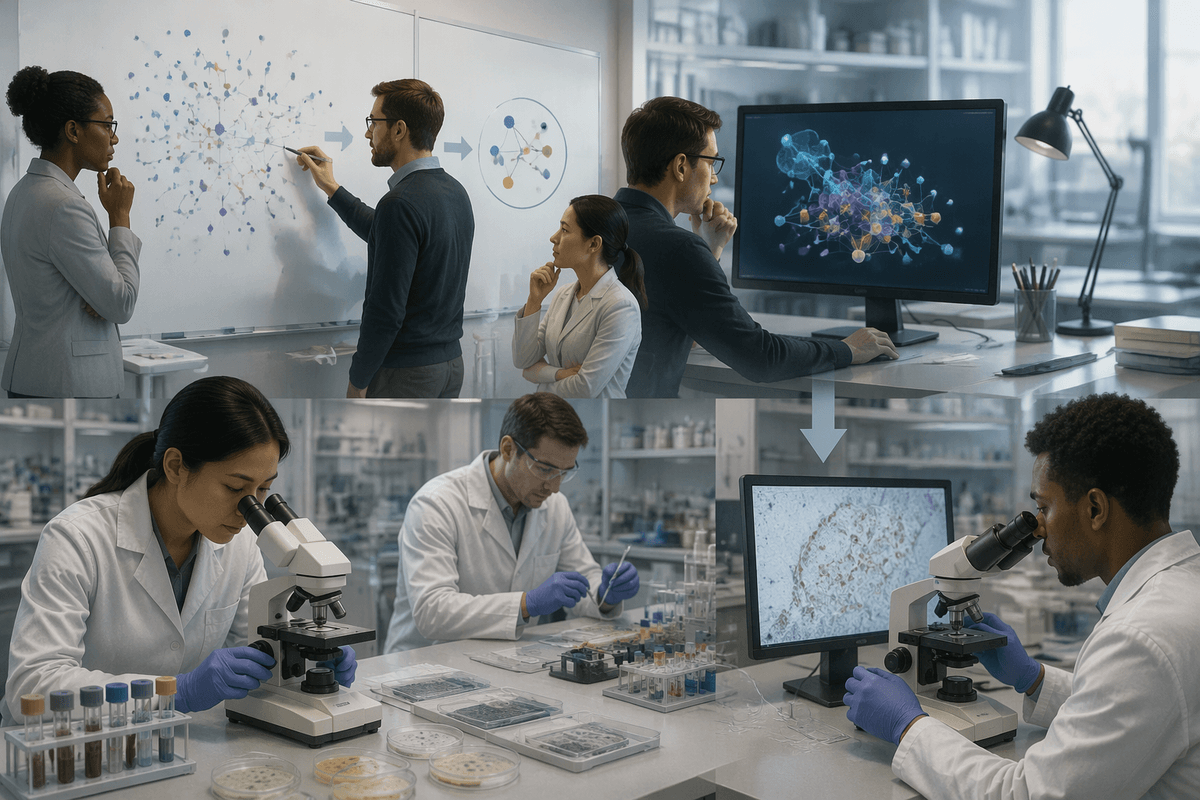
Other researchers could apply the lesson by starting with a narrowly defined question rather than trying to automate an entire field. They might use a modest model to compare studies, classify recurring findings, or identify which variables are often discussed together. The goal would be to produce a shortlist of relationships worth examining, then check those relationships against independent data or a different group of papers. This approach can be useful in fields where evidence is abundant but fragmented.
The method depends heavily on what researchers choose to include and measure. A dataset may leave out negative results, underrepresent certain populations, or use labels that make unrelated findings appear similar. Applying the lesson therefore requires transparent selection rules, repeated tests, and enough domain knowledge to challenge the model’s suggestions. Researchers do not need to treat AI as an oracle. They can use it as a practical screening tool: efficient enough to widen the search, limited enough that every important claim still receives human and experimental scrutiny.
The Bigger Shift Is Better Questions
The broader lesson is not that every research problem needs AI. It is that better tools can help researchers ask more precise questions. Instead of asking whether a model can predict an outcome, they can ask which evidence is connected, which assumptions remain untested, and where a small additional study could make the greatest difference. Those questions are easier to investigate because they turn a vague problem into a set of specific comparisons.
That shift also changes how success is measured. A useful system may not deliver a breakthrough or a definitive answer. It may show that researchers have been grouping unlike cases together, overlooking a population, or relying on a relationship that needs stronger testing. The practical standard is therefore modest but demanding: use simple AI to make uncertainty clearer, direct attention toward promising evidence, and leave the final judgment to research that can withstand closer scrutiny.