Why Generative AI Changes the Basis of Competition
Generative AI is changing how organizations think about competitive advantage. For years, companies often competed through scale: more employees, larger facilities, broader distribution, or greater spending on established technology. AI can alter that balance by allowing smaller teams to produce, analyze, and adapt more work. The important question is no longer simply who has access to a model, but who can turn that access into a repeatable capability.
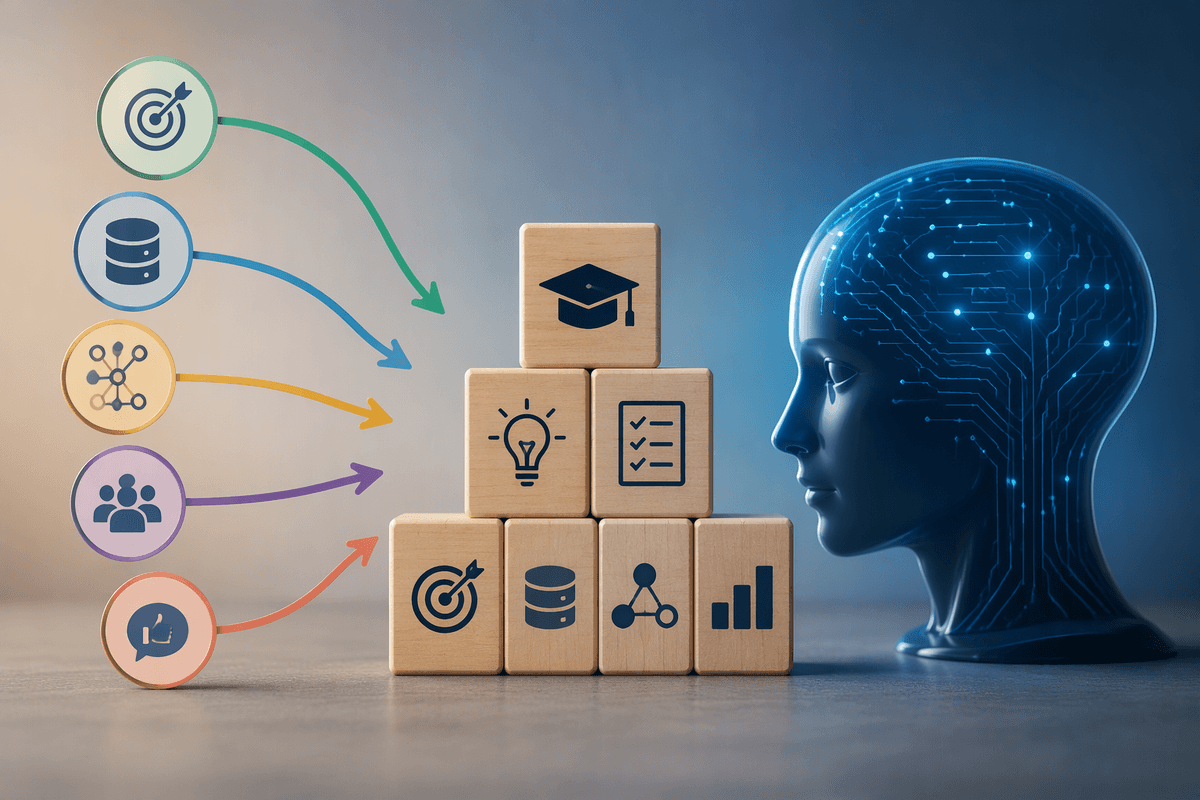
Model access is becoming a foundation rather than a complete strategy. Similar tools may be available to companies in the same industry, yet their outcomes can differ because of data quality, process design, talent, and customer relationships. A model can draft a useful response, but the organization must decide what the response should accomplish, which information it may use, and how a person will review it.
This creates a broader view of competition. Companies may compete on the speed with which they test ideas, the quality of their feedback, and the degree to which AI is connected to real work. An insurer, retailer, manufacturer, or media company can gain an advantage when its systems help employees make better decisions repeatedly, not merely when a demonstration looks impressive.
The shift also affects customers and workers. Some tasks may become easier, faster, or more personalized, while expectations for service and output rise. Organizations that use AI only to reduce visible labor may miss opportunities to redesign the customer experience. The durable advantage is likely to come from combining machine capability with human judgment and industry understanding.
It may also change how leaders measure productivity. Counting generated drafts or automated actions says little about whether a customer received a better answer or whether a team made a sounder decision. Strategic value appears when AI improves the quality, speed, or reach of an important activity without creating hidden correction costs.
Models, Proprietary Data, and Defensible Assets
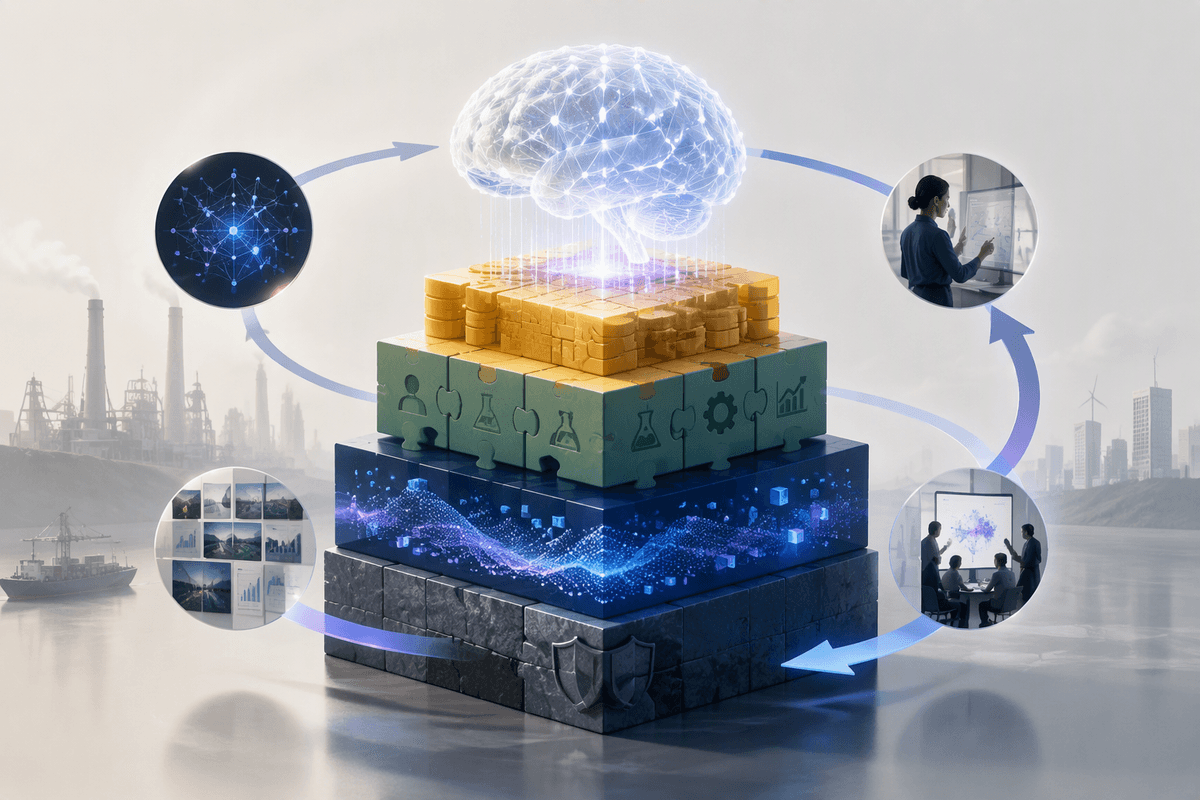
Generative models are powerful general-purpose tools, but useful business performance often depends on the material surrounding them. Proprietary data can include product histories, operational records, customer questions, internal procedures, design libraries, or domain-specific language. Its value comes not only from volume but from relevance, organization, permission, and the ability to connect it to a real decision.
High-quality data gives an organization a way to make a generic capability more specific. A company can provide approved terminology, examples of successful work, relevant constraints, and records of previous outcomes. This context may help an assistant produce responses that fit the organization’s standards rather than generic answers that require extensive correction.
Data alone is not automatically defensible. It must be maintained, governed, and connected to feedback. If users can mark an answer as useful, correct a classification, or explain why a recommendation failed, the organization can learn from those interactions. Over time, the feedback loop may improve prompts, retrieval, workflows, and evaluation criteria even when the underlying model is shared with competitors.
Domain knowledge is another asset. Experts understand which distinctions matter, which sources are trustworthy, and which exceptions can change a decision. Their knowledge can be expressed through procedures, review rules, examples, and carefully designed interfaces. This turns expertise into a shared organizational capability while keeping humans involved where interpretation is most important.
Organizations also need to consider rights and stewardship. Data used for AI must be handled in ways consistent with its permissions and sensitivity. A proprietary collection creates value only when the company can use it responsibly, protect it, and explain how it contributes to an outcome. Clean, well-described data can matter more than a larger but poorly governed collection.
Embedding AI Into Real Workflows
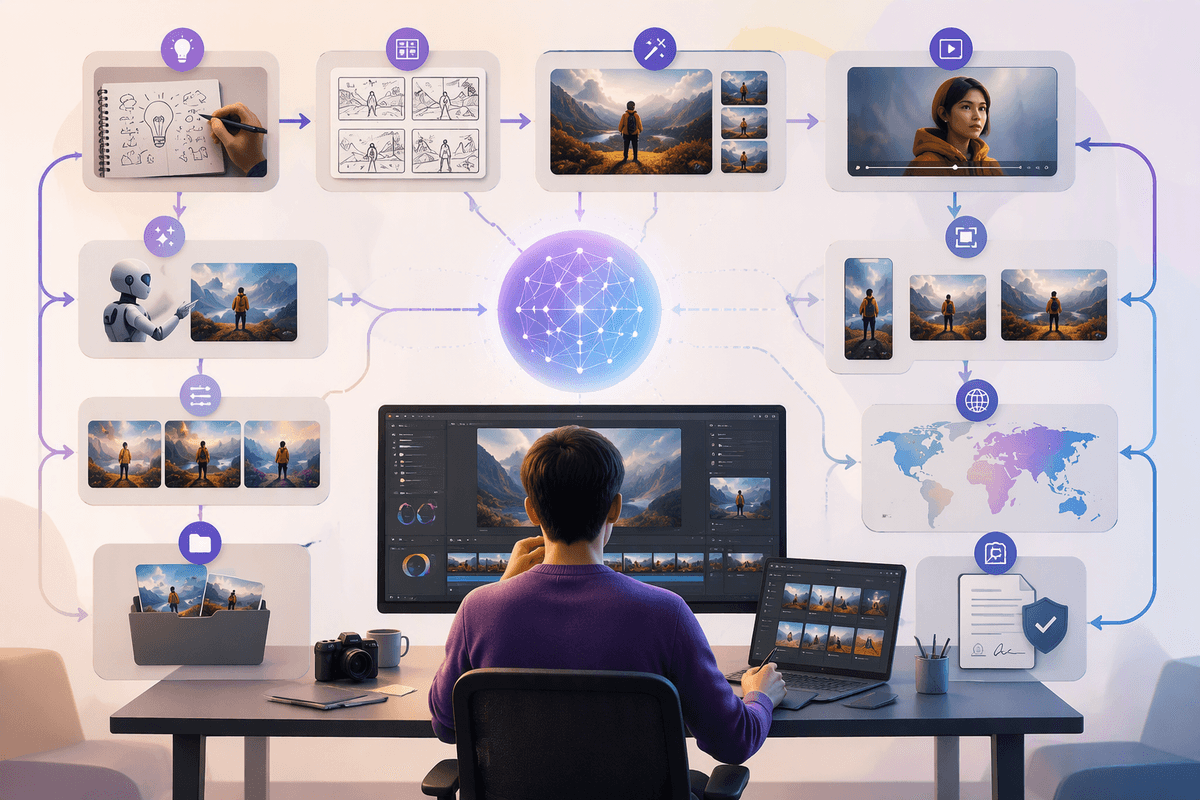
Implementation determines whether an AI project becomes a useful business process or remains an isolated experiment. A tool that generates text in a separate window may save time for one employee, but a connected workflow can route information, request approvals, update records, and make the result available to the next person. The difference is process integration.
Successful integration begins by identifying a specific bottleneck. A team might spend too much time classifying requests, preparing routine summaries, searching internal knowledge, or adapting a document for multiple audiences. AI can assist with these activities, but the organization should define the desired result, the acceptable error level, and the point where a human must intervene.
Process redesign is often more important than model selection. A company may need to simplify an intake form, standardize terminology, remove duplicate approvals, or clarify who owns a decision before automation can help. If a confusing process is merely given an AI interface, the confusion may become faster and harder to see.
Integration also requires evaluation. Teams can create representative examples, compare outputs with an agreed standard, and track recurring failure patterns. Evaluation should include more than fluency. It may cover completeness, consistency, safety, time saved, customer impact, and the effort required to correct an answer. These measures help leaders decide whether a use case deserves expansion.
Good design keeps a fallback available. Employees should be able to inspect inputs, edit results, report errors, and complete the task manually when the system is uncertain. This makes adoption less risky and provides the feedback needed to improve the workflow.
Integration can create an operational memory. When prompts, corrections, approvals, and exceptions are documented, later teams do not have to rediscover the same lessons. That record helps organizations distinguish a genuinely improved process from a temporary burst of enthusiasm around a new tool.
Distribution, Talent, and Organizational Capability
Even a strong AI capability needs a path to users. Companies with established customer relationships, trusted brands, distribution channels, or embedded software may introduce AI features more easily because the audience is already present. This can make distribution as important as technical performance. A useful assistant that reaches the right users at the right moment may create more value than a stronger tool that sits outside the customer’s normal routine.
Talent is changing as well. Organizations need people who understand both the business problem and the limits of AI. Engineers may build integrations, domain experts may define quality standards, and operators may monitor results. The most valuable teams can move between these perspectives rather than treating technology and operations as separate worlds.
Leadership influences whether experimentation becomes learning. Employees are more likely to use AI responsibly when managers provide clear goals, acceptable-use guidance, review expectations, and time to improve processes. If leaders demand adoption without explaining accountability, workers may hide errors or use tools in inconsistent ways.
Organizational learning can become a competitive asset. A company that captures lessons from pilots, shares reusable components, and retires weak ideas quickly may improve faster than a company that runs many disconnected demonstrations. Training should include how to frame a task, assess an output, protect sensitive information, and communicate uncertainty to colleagues or customers.
Distribution and talent reinforce one another. Feedback from real users helps improve the product, while skilled teams turn that feedback into changes. Over time, this relationship can make an AI-enabled service more relevant and harder to copy than a feature considered in isolation.
Speed, Experimentation, and Industry Change
Generative AI lowers the cost of trying some ideas, which can change the pace of competition. Teams can prototype a service, draft a campaign, test an interface, or simulate a support workflow before committing to a large production effort. The advantage comes from learning quickly, not from launching every experiment.
Fast experimentation requires discipline. Each test should have a clear question, a defined audience, and a way to decide what happens next. A prototype that receives positive reactions may still fail under real constraints such as privacy, reliability, cost, or integration. Conversely, an experiment that exposes a problem early can be valuable even when it is not shipped.
Business models may evolve as production becomes more flexible. Companies could offer more personalized services, deliver smaller batches of content, or combine software with expert review. Partnerships may also change as organizations share data, distribution, specialist knowledge, or workflow infrastructure. These arrangements create opportunities but also raise questions about ownership, dependency, and control.
Industry ecosystems can become more fluid. Suppliers may move closer to customers, platforms may add competing capabilities, and specialized firms may build services on top of shared models. The boundary between a product, a service, and an internal process may become less distinct. Companies need to decide which capabilities should be built, bought, partnered on, or kept proprietary.
Strategic risks remain. Overreliance on one provider can limit flexibility, while rushed deployment can damage trust. A competitor can copy a visible feature, making continuous improvement essential. Leaders must also consider whether an AI system changes bargaining power among suppliers, workers, customers, and platforms.
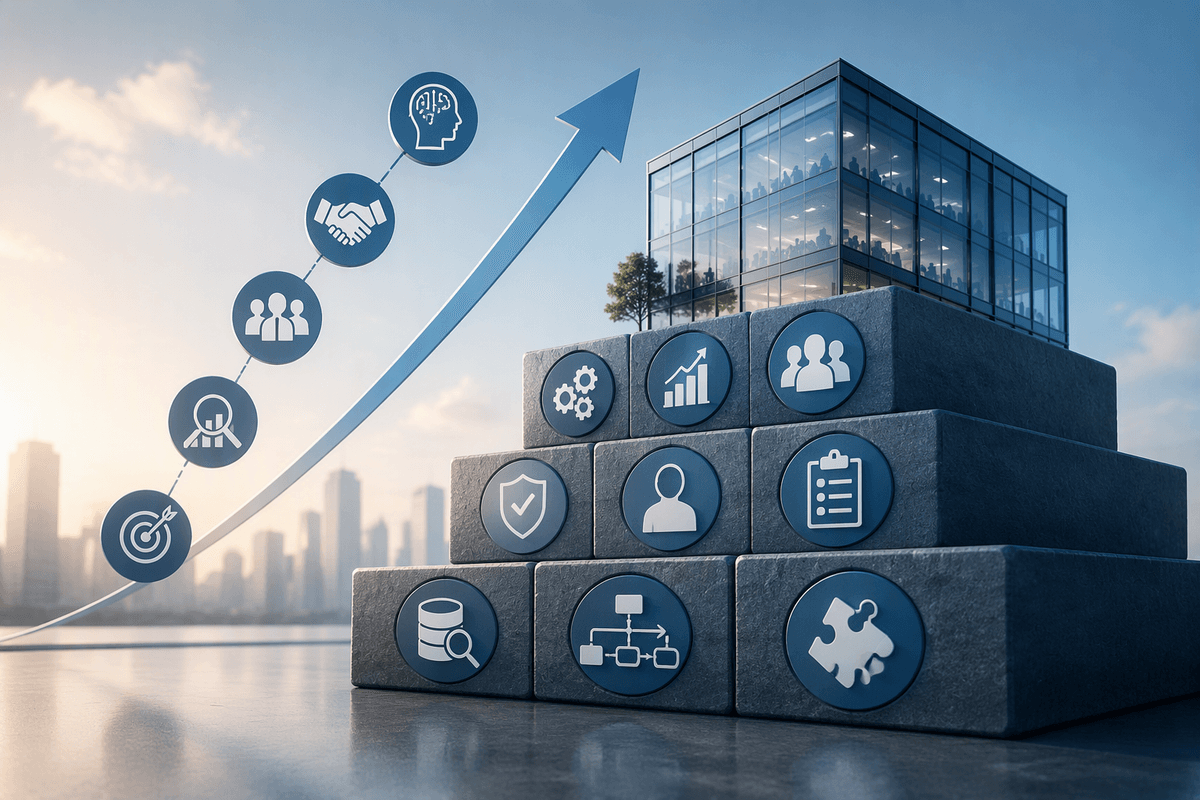
Generative AI therefore rewrites competitive advantage through a combination of assets: models, data, integration, distribution, talent, and learning speed. Organizations that connect those assets to meaningful customer and operational outcomes will be better positioned than those that treat AI as a novelty layered onto existing work. The winners will not necessarily be those with the most experiments, but those that turn experiments into dependable capabilities.